Gaussian scenes.
Parallel GPU simulation.
A self-contained simulator for the reconstructed UR5, RG2 gripper and wrist camera. Multiple approaches tested on one RTX A6000, with visual correctness checked against the original environment.
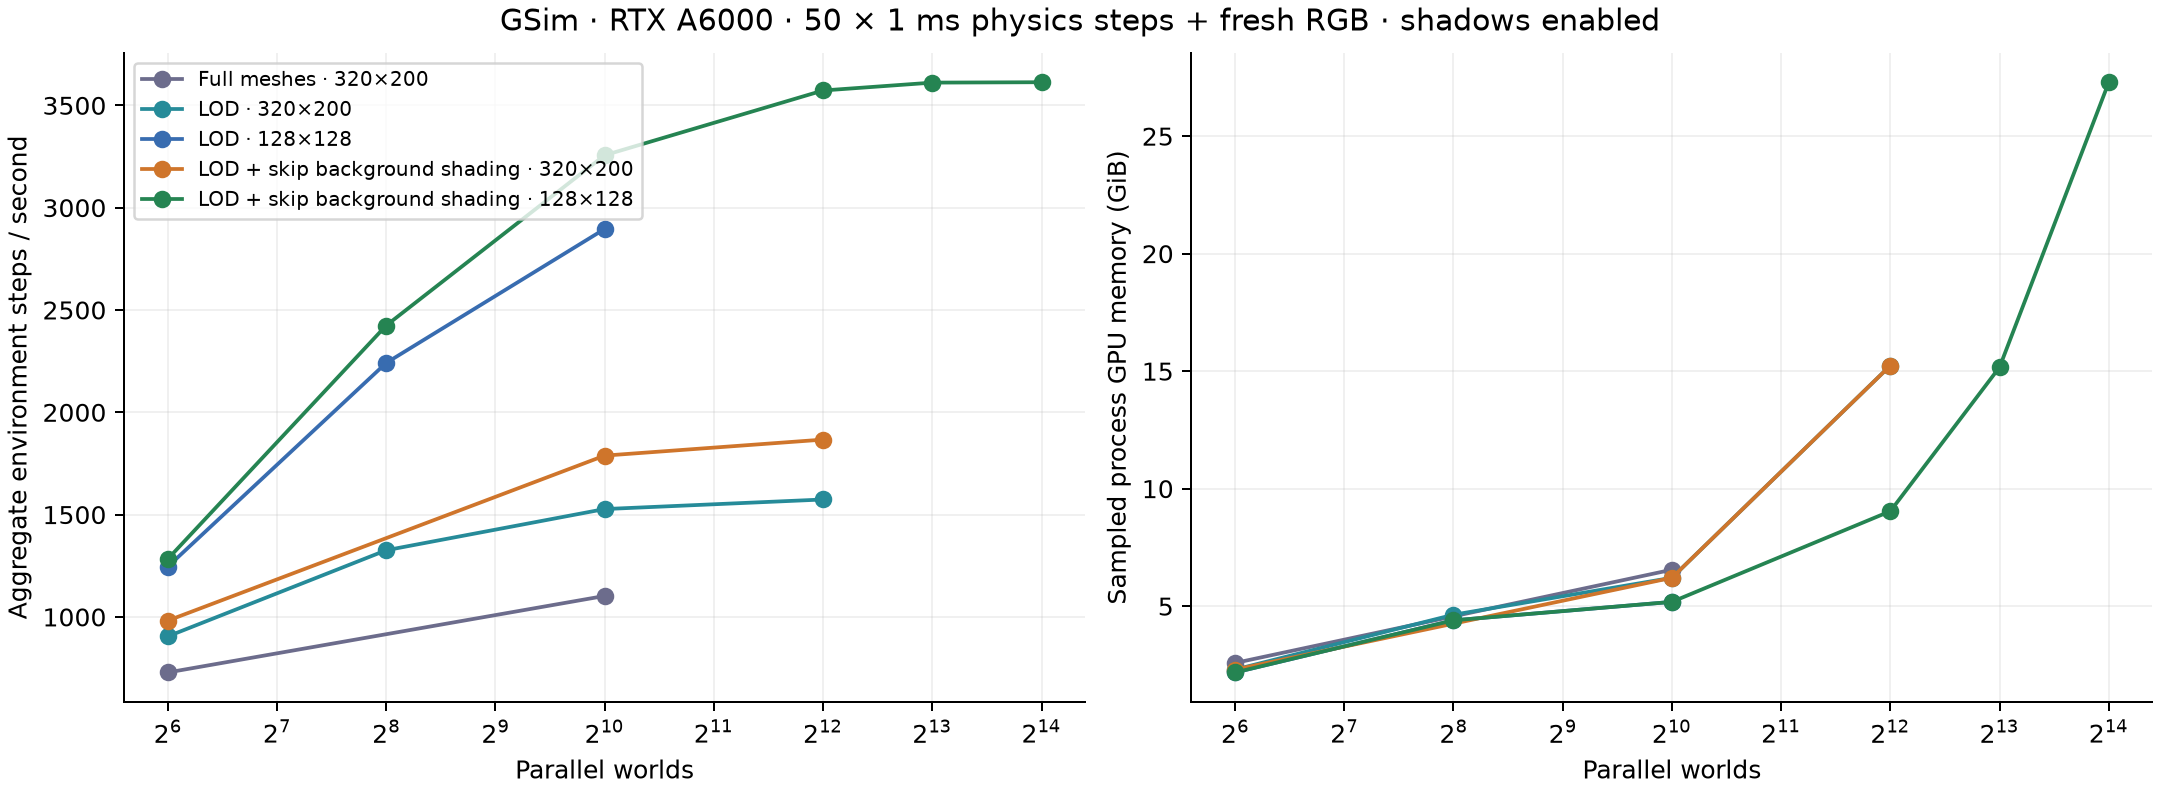
Full benchmark report ↓Raw measurements ↓Methods128×128 RGB · 16,384 worlds
NVML sampling · includes Warp + Torch
Independent physics state · shared scene
Each observation includes 50 physics steps at 1 ms plus fresh RGB. Aggregate throughput is not per-world frame rate: the fastest configuration takes 4.53 seconds per batch. No RL policy is included.
The configuration to build on
MJLab / MuJoCo Warp physics + calibrated, batched gsplat + a reference-compatible foreground renderer. Keep full degree-three appearance, enable shadows, and use chunks of 128 cameras. Simplified room/base visual meshes offer a measured speed–accuracy tradeoff; physical collision geometry is preserved.
18× lower Gaussian renderer memory
At 4,096 views, chunking reduced Torch allocation from about 38,962 to 2,152 MiB while retaining roughly 6.4k images/s. These are renderer-only measurements.
Camera and lighting repaired
Near-plane clipping and textured lighting needed explicit compatibility fixes. The faster raw Warp images failed the visual gate; the corrected renderer passes.
Stock MuGS did not run correctly
Its mask expansion is incompatible with current two-channel segmentation. Camera and SH-loading assumptions also differ from this scene.
Rasterization prototype failed quality
nvdiffrast ran on CUDA, but vertex-baked table textures lost detail without improving useful throughput. Lossy SH and radius shortcuts were also rejected.
Qualified physics + RGB measurements
All rows use shadows, calibrated cameras, SH degree 3, packed rendering, 128-camera chunks and 50 physics substeps. LOD means simplified room/base visibility meshes. “Skip background shading” omits lighting for mesh colors subsequently replaced by Gaussians.
| Renderer | RGB size | Worlds | Env steps/s | Batch ms | Process GiB |
|---|---|---|---|---|---|
| LOD | 128×128 | 64 | 1,245 | 51.4 | 2.18 |
| LOD + skip background shading | 128×128 | 64 | 1,283 | 49.9 | 2.18 |
| LOD | 128×128 | 256 | 2,241 | 114.2 | 4.40 |
| LOD + skip background shading | 128×128 | 256 | 2,424 | 105.6 | 4.40 |
| LOD | 128×128 | 1,024 | 2,896 | 353.6 | 5.18 |
| LOD + skip background shading | 128×128 | 1,024 | 3,256 | 314.5 | 5.18 |
| LOD + skip background shading | 128×128 | 4,096 | 3,573 | 1,146.5 | 9.04 |
| LOD + skip background shading | 128×128 | 8,192 | 3,611 | 2,268.6 | 15.17 |
| LOD + skip background shading | 128×128 | 16,384 | 3,613 | 4,534.8 | 27.29 |
| LOD | 256×256 | 1,024 | 1,357 | 754.4 | 5.75 |
| Full meshes | 320×200 | 64 | 729 | 87.8 | 2.58 |
| LOD | 320×200 | 64 | 905 | 70.7 | 2.30 |
| LOD + skip background shading | 320×200 | 64 | 982 | 65.2 | 2.30 |
| LOD | 320×200 | 256 | 1,326 | 193.1 | 4.63 |
| Full meshes | 320×200 | 1,024 | 1,102 | 928.8 | 6.55 |
| LOD | 320×200 | 1,024 | 1,527 | 670.5 | 6.21 |
| LOD + skip background shading | 320×200 | 1,024 | 1,788 | 572.6 | 6.21 |
| LOD | 320×200 | 4,096 | 1,574 | 2,602.5 | 15.24 |
| LOD + skip background shading | 320×200 | 4,096 | 1,867 | 2,194.4 | 15.24 |
Two warmups and eight synchronized samples per callable. Medians shown; raw data includes p95, samples, initialization time and runtime checks. Shared host conditions apply.
Visual match, measured before recommending
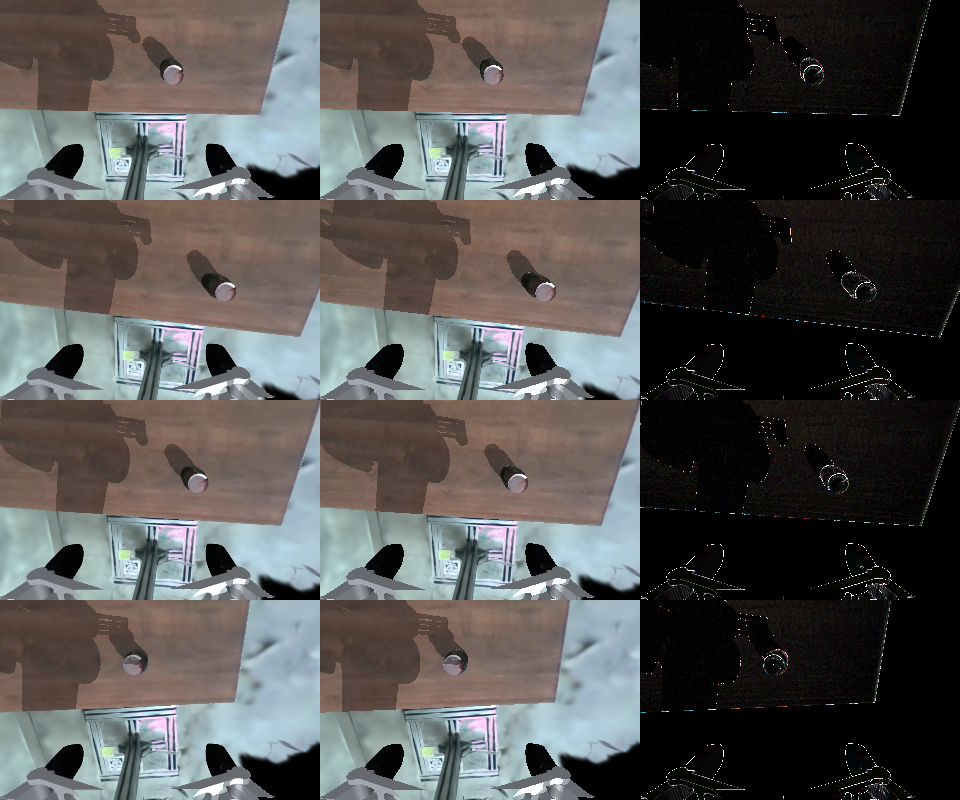
Eight wrist poses compared with the original renderer at 320×200. Full meshes exceed 99.99% silhouette overlap; simplified meshes exceed 99.5%. Shared Gaussian background error stays below 0.0003/255.
| Candidate | Foreground IoU | Whole-image mean absolute error |
|---|---|---|
| Full meshes | 99.9943–99.9977% | 0.984–1.508 / 255 |
| Simplified meshes | 99.5256–99.6782% | 1.105–1.757 / 255 |
Inspect the simplified-mesh comparison
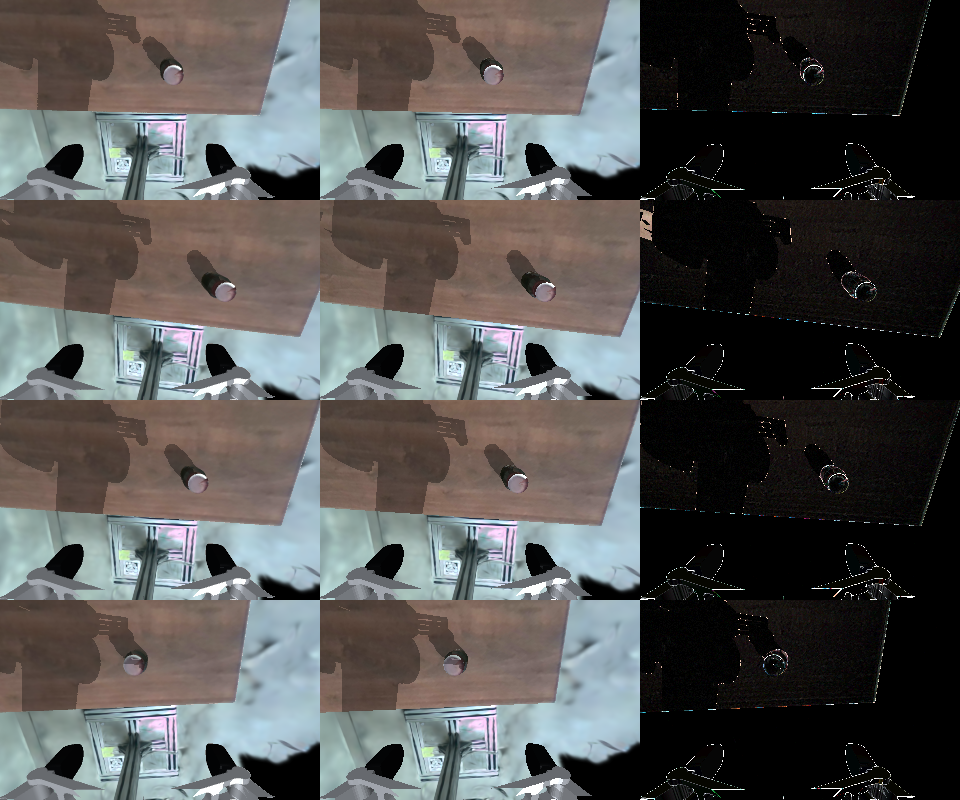
At 500 matched physics steps, arm error was 1.94e-6 radians and bottle position error was 0.233 mm. Changing one world leaves other images unchanged; resetting it restores its image exactly.
64 worlds in motion
Independent simulator copy
Assets, Gaussians, calibration, simulator code, packages and the CUDA build toolchain live in ~/GSim, beside ~/rl_training. Runtime does not read the old project folders.
Six reference frames match pixel for pixel; qpos/qvel are identical. All 163 XML asset paths resolve locally. MJLab's tracked source is unchanged.
Source hashes and package versions
What remains different
GPU-resident bulk data, with small host synchronizations. State, transforms and images stay on CUDA during stepping, but gsplat performs three scalar device-to-host reads per render chunk. Initialization is CPU-assisted.
Contact equivalence is incomplete. The short trajectory passes, but CPU MuJoCo produces five bottle contacts where this Warp path produces one per world. Long grasps and task success still need qualification.
A benchmark adapter, not an RL task yet. It accepts joint actuator targets. Cartesian IK, rewards, termination, policy inference, heterogeneous scenes and large-scale randomization are outside the measured scope.
ManiSkill / SAPIEN: published reference only
ManiSkill/SAPIEN was not installed or run. These official published results use one 128×128 RGB camera and an RTX 4090.
| Published task | Worlds | Env steps/s | Reported GPU GiB |
|---|---|---|---|
| PickCube-v1 | 64 | 6,673 | 1.90 |
| PickCube-v1 | 256 | 12,904 | 2.20 |
| PickCube-v1 | 1,024 | 17,472 | 3.08 |
| CartpoleBalanceBenchmark-v1 | 64 | 21,889 | 1.77 |
| CartpoleBalanceBenchmark-v1 | 256 | 30,344 | 2.01 |
| CartpoleBalanceBenchmark-v1 | 1,024 | 32,138 | 2.88 |
These tasks use two physics steps per image, versus GSim's 50. Hardware, scene, robot, contacts and renderer differ. Equal-compute parity has not been demonstrated. See the official methodology and full report.
All pipeline attempts and timing ablations
Historical no-shadow, one-substep and experimental runs are not equivalent to the qualified rows. Completed timing means runtime checks passed; visual quality is assessed separately.
| Run identifier | Recorded outcome |
|---|---|
| graph_128x128_n1024 | 3,219 env steps/s |
| graph_128x128_n256 | 2,394 env steps/s |
| graph_128x128_n4096 | 3,526 env steps/s |
| graph_128x128_n64 | 1,262 env steps/s |
| graph_256x256_n1024 | 1,606 env steps/s |
| graph_256x256_n256 | 1,377 env steps/s |
| graph_256x256_n4096 | 1,672 env steps/s |
| graph_256x256_n64 | 913 env steps/s |
| graph_320x200_n1024 | 1,534 env steps/s |
| graph_320x200_n256 | 1,322 env steps/s |
| graph_320x200_n4096 | 1,594 env steps/s |
| graph_320x200_n64 | 890 env steps/s |
| hybrid_n1 | 36 env steps/s |
| hybrid_n1024 | 1,544 env steps/s |
| hybrid_n256 | 1,327 env steps/s |
| hybrid_n4096 | 1,599 env steps/s |
| hybrid_n64 | 905 env steps/s |
| lod_128x128_n1024 | 4,139 env steps/s |
| lod_128x128_n4096 | 4,705 env steps/s |
| lod_128x128_n8192 | 4,764 env steps/s |
| lod_320x200_n1024 | 2,159 env steps/s |
| lod_320x200_n4096 | 2,272 env steps/s |
| lod_320x200_n64 | 1,089 env steps/s |
| mugs_n1 | Error: The expanded size of the tensor (3) must match the existing size (2) at non-singleton dimension 3. Target sizes: [-1, -1, -1, 3]. Tensor sizes: [1, 200, 320, 2] |
| native_n1 | 38 env steps/s |
| native_n1024 | 2,080 env steps/s |
| native_n256 | 1,703 env steps/s |
| native_n4096 | 2,172 env steps/s |
| native_n64 | 1,045 env steps/s |
| one_step_128_n1024 | 3,727 env steps/s |
| one_step_128_n4096 | 3,772 env steps/s |
| qualified_full_320x200_n1024 | 1,102 env steps/s |
| qualified_full_320x200_n64 | 729 env steps/s |
| qualified_lod_128x128_n1024 | 2,896 env steps/s |
| qualified_lod_128x128_n256 | 2,241 env steps/s |
| qualified_lod_128x128_n64 | 1,245 env steps/s |
| qualified_lod_256x256_n1024 | 1,357 env steps/s |
| qualified_lod_320x200_n1024 | 1,527 env steps/s |
| qualified_lod_320x200_n256 | 1,326 env steps/s |
| qualified_lod_320x200_n4096 | 1,574 env steps/s |
| qualified_lod_320x200_n64 | 905 env steps/s |
| qualified_skipbg_128x128_n1024 | 3,256 env steps/s |
| qualified_skipbg_128x128_n16384 | 3,613 env steps/s |
| qualified_skipbg_128x128_n256 | 2,424 env steps/s |
| qualified_skipbg_128x128_n4096 | 3,573 env steps/s |
| qualified_skipbg_128x128_n64 | 1,283 env steps/s |
| qualified_skipbg_128x128_n8192 | 3,611 env steps/s |
| qualified_skipbg_320x200_n1024 | 1,788 env steps/s |
| qualified_skipbg_320x200_n4096 | 1,867 env steps/s |
| qualified_skipbg_320x200_n64 | 982 env steps/s |
| raster_lod_n1 | 34 env steps/s |
| raster_lod_n64 | 915 env steps/s |
| rejected_aspect_qualified_lod_128x128_n1024 | 3,225 env steps/s |
| rejected_aspect_qualified_lod_128x128_n16384 | 3,575 env steps/s |
| rejected_aspect_qualified_lod_128x128_n256 | 2,406 env steps/s |
| rejected_aspect_qualified_lod_128x128_n4096 | 3,547 env steps/s |
| rejected_aspect_qualified_lod_128x128_n64 | 1,283 env steps/s |
| rejected_aspect_qualified_lod_128x128_n8192 | 3,576 env steps/s |
| rejected_aspect_qualified_lod_256x256_n1024 | 1,583 env steps/s |