STATE TEACHER · SIMULATION ONLY
superdex_gs RL teacher
A privileged-state teacher for the UR5 + RG2 bottle pick, trained in superdex_gs as the first stage of the teacher → image-student plan. The final teacher was behaviour-cloned from a privileged scripted expert and then fine-tuned with PPO under a domain-randomization curriculum; PPO from random weights learned to grasp and lift but never passed the strict 2 s hold. All attempts, their diagnoses and held-out results are below.
Strict success: bottle bottom ≥10 cm above the tabletop, both pads ≥0.05 N, bottle stable, held 2 s, within a 15 s episode. Evaluations use the deterministic (mean) action, fresh seeds, and each environment's first episode. Rates below 100% at wide randomization include layouts outside the arm's top-down reach; the privileged scripted expert is shown on the same seeds as a reference ceiling.
Teacher contract
| Observation | 43-D privileged state: joint positions and velocities, TCP→bottle and bottle→goal vectors, previous action, bottle up-axis, pad contact forces, hold progress (with teacher observation noise). |
| Action | superdex-gs-cartesian-v1 7-D action; orientation held top-down (rotation outputs ignored) and binary gripper (output < 0 closes). Labels stay valid for the 7-D student. |
| Network / algorithm | rsl_rl 5.5 PPO, actor and critic MLP 256-128-64 ELU with observation normalization, 256 environments × 32 steps per update, adaptive learning rate (KL 0.01). |
| Reward (teacher-v5; selected checkpoint) | Staged above-then-descend reach and progress, centring, closing near the grasp point, bilateral contact (mostly once lifted), lift up to 15 cm, lift progress, holding reward ramping 9–13 cm, push-down / premature-closure / action-bound penalties, −0.5 on tip or fall, +100 once on strict success. A later continuation with teacher-v6 (pre-grasp disturbance penalty) did not improve validation and was not selected. |
| Curriculum | Teacher DR preset (layout, start pose, physics, observation noise, pushes). Scale starts at 0.1 and rises by 0.1 when a deterministic validation of the latest checkpoint (64 envs) reaches min(80%, 0.9 × the scripted expert on the same seeds). |
Held-out evaluation
Checkpoint selection (highest mean strict success over validation scales 0.3, 0.6, 1.0 (seed 5001, 64 envs each)); selected ppo_bcft_v2_seed42_model_260. The final test below uses different seeds (9001, 128 environments per scale).
| Candidate | Validation | Mean |
|---|---|---|
| ppo_bcft_v1_seed42_model_180 | scale 0.3: 63/64, scale 0.6: 38/64, scale 1.0: 19/64 | 62.5% |
| ppo_bcft_v2_seed42_model_260 | scale 0.3: 64/64, scale 0.6: 41/64, scale 1.0: 18/64 | 64.1% |
| ppo_bcft_v3_seed42_model_380 | scale 0.3: 63/64, scale 0.6: 34/64, scale 1.0: 15/64 | 58.3% |
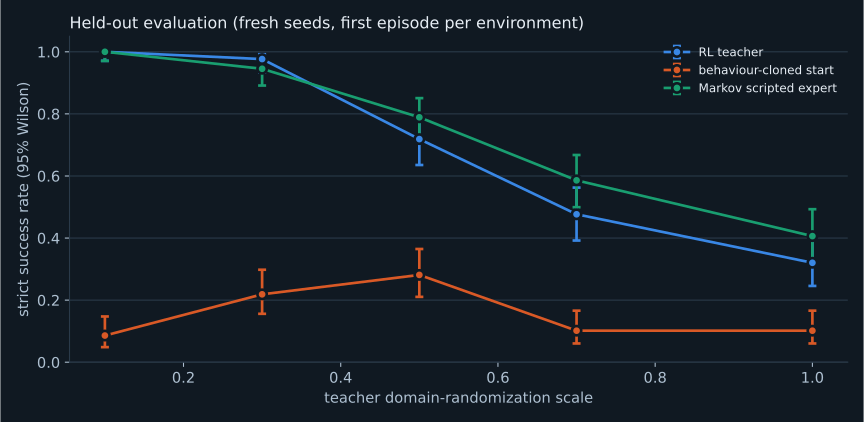
| DR scale | RL teacher | behaviour-cloned start | Markov scripted expert |
|---|---|---|---|
| 0.1 | 128/128 (100%, CI 97%–100%) | 11/128 (9%, CI 5%–15%) | 128/128 (100%, CI 97%–100%) |
| 0.3 | 125/128 (98%, CI 93%–99%) | 28/128 (22%, CI 16%–30%) | 121/128 (95%, CI 89%–97%) |
| 0.5 | 92/128 (72%, CI 64%–79%) | 36/128 (28%, CI 21%–36%) | 101/128 (79%, CI 71%–85%) |
| 0.7 | 61/128 (48%, CI 39%–56%) | 13/128 (10%, CI 6%–17%) | 75/128 (59%, CI 50%–67%) |
| 1.0 | 41/128 (32%, CI 25%–41%) | 13/128 (10%, CI 6%–17%) | 52/128 (41%, CI 33%–49%) |
Teacher failure outcomes
| Scale | Outcomes |
|---|---|
| 0.1 | success 128 |
| 0.3 | success 125, tipped 3 |
| 0.5 | lifted, hold < 2 s 4, success 92, never bilaterally grasped 13, tipped 19 |
| 0.7 | never bilaterally grasped 44, success 61, tipped 21, lifted, hold < 2 s 2 |
| 1.0 | never bilaterally grasped 68, success 41, tipped 17, lifted, hold < 2 s 2 |
Videos
Left: third-person view. Right: the D415 wrist image rendered for the same state (the teacher itself uses privileged state only).
Training history
1. PPO from random weights (reward iterations)
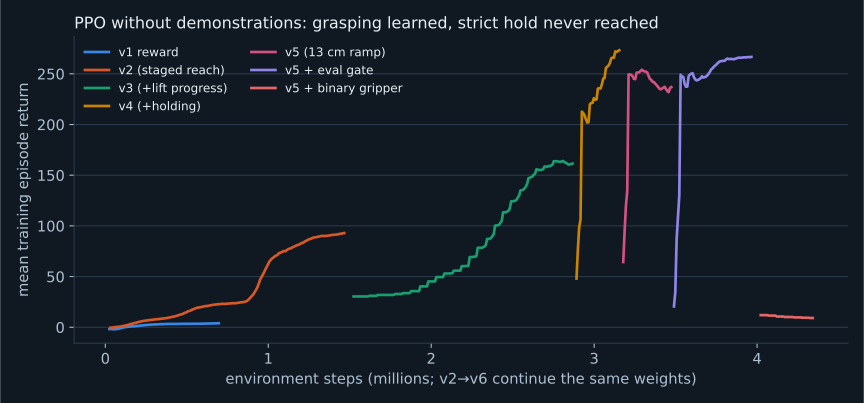
| Run | Env steps | Final return | Training success | What happened |
|---|---|---|---|---|
| v1 reward | 696,320 | 4 | 0% | diagnosis# ppo_v1_seed42 — stopped at iteration 85 (696,320 env steps) Reward `teacher-v1` (SuperDex YAM task v2 shaping), teacher DR scale 0.1, 256 envs. Rolling training success 0/512; mean return rose from −1.8 to 4.0 and plateaued. Deterministic rollout of `model_50.pt` (16 envs, 200 ticks): TCP settled 5.7 cm from the grasp point — 3.8 cm off the bottle axis and 4.3 cm below it (beside the bottle); mean raw gripper action +1.8 (beyond the +1 clip, fully open), no bilateral contact in any env. Cause: the closing bonus only paid within ~2.5 cm while premature closure was penalized everywhere else, the reach term rewarded descending beside the bottle, and unbounded raw gripper means saturated open, removing exploration. Revision `teacher-v2`: above-then-descend reach target, centring term, closing/contact reward ×5/×3, premature-closure penalty only beyond 5 cm, raw-action bound penalty. Reward ordering check (8 envs): scripted pick 200.0, hover open at grasp 13.7, beside bottle 1.2. |
| v2 (staged reach) | 1,466,368 | 93 | 0% | diagnosis# ppo_v2_seed42 — stopped at iteration ~180 (≈1.47 M env steps) Reward `teacher-v2`, teacher DR scale 0.1, 256 envs, from random weights. Mean training return rose from 0.2 to 92.7 and plateaued; rolling strict success 0/512 (4 bottles dropped after lifting during the whole run). Deterministic rollout of `model_150.pt` (16 envs, 200 ticks): bilateral grasp in 16/16 envs from tick ~40, but the z action stayed at −1 (pressing down) and no bottle was lifted (max clearance 0 cm). Local optimum: steady contact/closing reward while pressing down. Reward ordering was already correct (scripted pick 200 vs scripted grasp-and-press 36.7), so the obstacle was exploration of lifting. Revision `teacher-v3` (continues from this run's final weights): contact pays mostly once the bottle is above 1 cm, lift-progress reward (20 × clearance gain per tick while grasped), push-down penalty while grasped below 10 cm. Ordering: scripted pick 197.4, grasp-and-press 17.7. |
| v3 (+lift progress) | 1,400,832 | 161 | 0% | diagnosis# ppo_v3_seed42 — continued from ppo_v2_seed42 (iteration 179); stopped after 173 more iterations (≈1.42 M env steps) Reward `teacher-v3`. Mean training return rose from ~30 to ~162 and plateaued; lifts began (≈110 bottles lifted then dropped) but rolling strict success stayed 0/512. Forced-lift probe on `model_200.pt`: the learned grasp is centred within 4 mm at the planned height and lifts every bottle past 10 cm with bilateral contact when z = +1 is commanded, so physics and grasp quality were not the obstacle. Deterministic rollout of `model_300.pt`: bilateral grasp and lift in 16/16 envs, then hover at 4.4–5.7 cm clearance with z ≈ 0; no tick above 10 cm. Scripted pick vs scripted hover-at-5 cm returned 197 vs 151 under v3 — too small a margin, and success terminated the episode, cutting off further reward. Revision `teacher-v4`: lift reward ×1.5, lift progress ×2 below 13 cm, holding reward 1.0 per tick when grasped, stable and ≥10 cm, and episodes no longer end at success (hold keeps paying). |
| v4 (+holding) | 286,720 | 273 | 0% | diagnosis# ppo_v4_seed42 — continued from ppo_v3_seed42; stopped after 35 iterations (286,720 env steps) Reward `teacher-v4`, episodes continue after success. Return rose quickly (106 → 273). Deterministic `model_200.pt` (rsl iteration count) lifted all 16 bottles within ~3.5 s but settled at 10.0–10.2 cm clearance, exactly the success threshold; small dips reset the strict 2 s hold timer (max 0.2 s). Cause: step holding reward at 10 cm and lift reward saturating at 12 cm gave no margin above the threshold. Revision `teacher-v5`: lift saturates at 15 cm, holding reward ramps from 9 to 13 cm. Scripted pick-and-hold return under v5: 515.6 (8/8 success). |
| v5 (13 cm ramp) | 319,488 | 237 | 0% | diagnosis |
| v5 + eval gate | 491,520 | 267 | 0% | diagnosis# ppo_v5b_seed42 — continued from ppo_v5_seed42 (v5 reward, eval-gated curriculum); stopped after ~90 iterations Deterministic validations (64 envs, scale 0.1): model_50 0/64 and model_75 0/64 strict successes; all 64 lifted but held at 10.1–10.2 cm max clearance. Per-tick v5 reward for the scripted hold rose from 1.76 at 9.9 cm to 2.87 at 13.4 cm, so the reward favoured higher holds. Forced-lift probe from the policy's hover state: z = +1 with the policy's own gripper output dropped the bottles within 0.5 s (its gripper command drifted from −0.84 toward −0.6 as the state left the training distribution); z = +1 with gripper −1 lifted all 16 bottles to 29 cm. Cause: partial gripper closure. Revision: teacher uses a binary gripper (action < 0 fully closed), same reward. |
| v5 + binary gripper | 376,832 | 9 | 0% | diagnosis# ppo_v6_seed42 — continued from ppo_v5b_seed42 with a binary gripper; stopped after ~45 iterations Switching the gripper to binary (action < 0 fully closed) removed the partial-closure slip, but the inherited policy's gripper command crossed zero during approach, so it closed early and never grasped (deterministic validation 0/64 "never bilaterally grasped" at model_100 and model_125; training return fell from ~12 to ~9). PPO did not re-discover grasp timing in 45 iterations. Decision: stop reward iteration from scratch-trained weights and bootstrap the teacher from demonstrations of the privileged scripted expert (binary gripper commands, orientation locked), then fine-tune with PPO under the evaluation-gated curriculum. |
2. Demonstrations and behaviour cloning
A state-feedback (Markov) scripted expert was written so that every decision is observable (the timer-based expert's lift timing is not, and a first clone never lifted). 276,480 demonstration steps at scales 0.1, 0.3, 0.6; 30% of environments executed noisy actions while recording the clean expert label. Expert success on complete episodes: scale 0.1 99%, scale 0.3 97%, scale 0.6 70%. The clone (40 epochs, final action MSE 0.0041) grasped and lifted but succeeded rarely:
| Scale | Behaviour-cloned start | Outcomes |
|---|---|---|
| 0.1 | 6/64 | lifted, hold < 2 s 41, tipped 14, grasped, not lifted 10 cm 3, success 6 |
| 0.3 | 18/64 | success 18, tipped 17, lifted, hold < 2 s 17, grasped, not lifted 10 cm 11, never bilaterally grasped 1 |
| 0.6 | 11/64 | grasped, not lifted 10 cm 9, tipped 16, success 11, never bilaterally grasped 20, lifted, hold < 2 s 8 |
| 1.0 | 4/64 | grasped, not lifted 10 cm 9, never bilaterally grasped 28, lifted, hold < 2 s 8, tipped 14, success 4, bottle fell off table 1 |
3. PPO fine-tuning
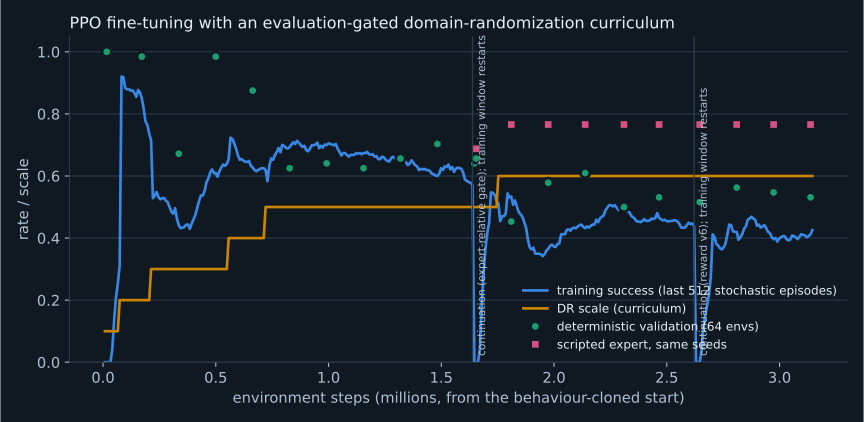
3,145,728 environment steps over three continuations (2.4 h at ≈370 steps/s including PPO updates and concurrent validation). Two training processes were terminated by the kernel OOM killer when a third 56-worker environment ran alongside training and validation (each physics worker holds ≈1.1 GiB); both continued from their last periodic checkpoint.
| Iteration | Scale | Validation | Gate | Run |
|---|---|---|---|---|
| 9 | 0.1 → 0.2 | 100% | 80% | ppo_bcft_v1_seed42 |
| 26 | 0.2 → 0.3 | 98% | 80% | ppo_bcft_v1_seed42 |
| 68 | 0.3 → 0.4 | 98% | 80% | ppo_bcft_v1_seed42 |
| 88 | 0.4 → 0.5 | 88% | 80% | ppo_bcft_v1_seed42 |
| 14 | 0.5 → 0.6 | 66% | 62% | ppo_bcft_v2_seed42 |
All deterministic validations
| Run | Checkpoint | Scale | Successes | Expert (same seeds) | Outcomes |
|---|---|---|---|---|---|
| ppo_bcft_v1_seed42 | model_0.pt | 0.1 | 64/64 | success 64 | |
| ppo_bcft_v1_seed42 | model_20.pt | 0.2 | 63/64 | success 63, tipped 1 | |
| ppo_bcft_v1_seed42 | model_40.pt | 0.3 | 43/64 | success 43, tipped 20, lifted, hold < 2 s 1 | |
| ppo_bcft_v1_seed42 | model_60.pt | 0.3 | 63/64 | success 63, tipped 1 | |
| ppo_bcft_v1_seed42 | model_80.pt | 0.4 | 56/64 | success 56, tipped 8 | |
| ppo_bcft_v1_seed42 | model_100.pt | 0.5 | 40/64 | grasped, not lifted 10 cm 4, never bilaterally grasped 4, tipped 15, success 40, lifted, hold < 2 s 1 | |
| ppo_bcft_v1_seed42 | model_120.pt | 0.5 | 41/64 | never bilaterally grasped 7, tipped 15, success 41, lifted, hold < 2 s 1 | |
| ppo_bcft_v1_seed42 | model_140.pt | 0.5 | 40/64 | never bilaterally grasped 8, tipped 12, grasped, not lifted 10 cm 1, success 40, bottle fell off table 2, lifted, hold < 2 s 1 | |
| ppo_bcft_v1_seed42 | model_160.pt | 0.5 | 42/64 | never bilaterally grasped 7, tipped 13, grasped, not lifted 10 cm 1, success 42, bottle fell off table 1 | |
| ppo_bcft_v1_seed42 | model_180.pt | 0.5 | 45/64 | never bilaterally grasped 12, success 45, tipped 7 | |
| ppo_bcft_v1_seed42 | model_200.pt | 0.5 | 41/64 | never bilaterally grasped 10, tipped 12, success 41, grasped, not lifted 10 cm 1 | |
| ppo_bcft_v2_seed42 | model_200.pt | 0.5 | 42/64 | 69% | never bilaterally grasped 14, success 42, tipped 7, grasped, not lifted 10 cm 1 |
| ppo_bcft_v2_seed42 | model_220.pt | 0.6 | 29/64 | 77% | tipped 22, success 29, never bilaterally grasped 11, bottle fell off table 2 |
| ppo_bcft_v2_seed42 | model_240.pt | 0.6 | 37/64 | 77% | success 37, tipped 13, never bilaterally grasped 13, bottle fell off table 1 |
| ppo_bcft_v2_seed42 | model_260.pt | 0.6 | 39/64 | 77% | success 39, never bilaterally grasped 14, tipped 8, lifted, hold < 2 s 2, bottle fell off table 1 |
| ppo_bcft_v2_seed42 | model_280.pt | 0.6 | 32/64 | 77% | success 32, never bilaterally grasped 13, tipped 15, lifted, hold < 2 s 4 |
| ppo_bcft_v2_seed42 | model_300.pt | 0.6 | 34/64 | 77% | success 34, never bilaterally grasped 13, tipped 16, lifted, hold < 2 s 1 |
| ppo_bcft_v3_seed42 | model_320.pt | 0.6 | 33/64 | 77% | success 33, never bilaterally grasped 13, tipped 17, grasped, not lifted 10 cm 1 |
| ppo_bcft_v3_seed42 | model_340.pt | 0.6 | 36/64 | 77% | success 36, never bilaterally grasped 13, tipped 15 |
| ppo_bcft_v3_seed42 | model_360.pt | 0.6 | 35/64 | 77% | success 35, never bilaterally grasped 13, tipped 15, grasped, not lifted 10 cm 1 |
| ppo_bcft_v3_seed42 | model_380.pt | 0.6 | 34/64 | 77% | success 34, never bilaterally grasped 14, tipped 16 |
Limitations
- The teacher depends on demonstrations from a privileged scripted expert; PPO from scratch did not reach strict success within ≈4.3 M steps.
- Orientation is fixed top-down and the gripper is binary; layouts needing a tilted grasp are counted as failures.
- Knocking the bottle over during approach remains the main failure at wider randomization.
- No image student exists yet; no real-robot evaluation.
Raw artifacts
report/summary.json · bc_start/summary.json · expert/summary.json · teacher/summary.json · ppo_bcft_v1_seed42/curriculum.json · ppo_bcft_v1_seed42/evaluations.jsonl · ppo_bcft_v2_seed42/curriculum.json · ppo_bcft_v2_seed42/evaluations.jsonl · ppo_bcft_v3_seed42/evaluations.jsonl