SIMULATOR · SIMULATION ONLY
superdex_gs: SuperDex physics + Gaussian-splat D415 wrist camera
A standalone simulator for the UR5 CB3 + OnRobot RG2 bottle pick with the new RealSense D415 on mount v4. SuperDex supplies the contact physics (the engine where state-only PPO learned this pick); the calibrated mjlab_gs rendering stack supplies the wrist image (Warp mesh foreground over a 155k-Gaussian room). One vectorized environment serves the privileged state teacher and the image student, with every domain-randomization family from policy_training, mjlab_gs and rl_training.
Next stage: state RL teacher trained in superdex_gs →
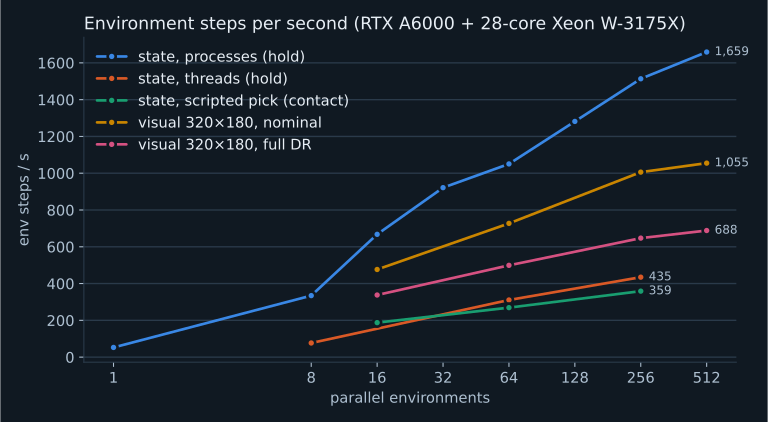
Hardware: one RTX A6000 (rendering) and a 28-core / 56-thread Xeon W-3175X (physics). Throughput is total environment steps per second across all parallel environments at 20 Hz control with 2 ms physics. Evidence below is from the scripts named in each section; the scripted expert is privileged and is not a learned policy.
What was built
| Scene | mjlab_gs calibrated room, table, pedestal, UR5 CB3 and legacy RG2 with the D455 replaced by the D415 on mount v4. D415 colour factory intrinsics 1280×720 (fx 913.94, fy 912.14); optical centre matches the CAD metadata to 2.5e-15 m; vertical FOV 43.08°. |
| Physics | MJCF robot converted to a SuperDex articulation (22 links incl. welded convex-hull collision links); RG2 parallelograms closed with cycle joints and two symmetric torque-limited drives; bottle scan surface as SDF; 4 cm table slab, cabinet, pedestal and floor. 2 ms implicit steps, 25 per 20 Hz tick. |
| Control | 7-D base-frame Cartesian actions (5 mm, 1° per tick), damped-least-squares IK and analytic gravity compensation at 125 Hz, gripper linkage target; contract superdex-gs-cartesian-v1. |
| Parallelism | Each worker process owns a block of SuperDex scenes and runs whole ticks (IK + physics) with shared-memory state; the main process batches DR, observations, rewards, success and GPU rendering. A thread backend is kept for comparison. |
| Rendering | Render-only mujoco_warp model fed with SuperDex poses, mjlab_gs's calibrated Warp foreground with shadows and textures, gsplat room with the pedestal field moved per world, CUDA-graph capture (57 ms → 0.40 ms per image), per-world camera, light, material, texture, background and image randomization. |
| Tasks | State teacher: 43-D privileged observation. Visual student: 16-D proprioception + 3-D goal + 180×320 RGB; 61-D critic. Strict success: ≥10 cm clearance, bilateral pad contact, stable, held 2 s. Details: TASK.md, README.md. |
Issues found and fixed while validating
| Symptom | Cause | Fix (before the final measurements) |
|---|---|---|
| RG2 linkage jammed at 0.05 rad | SuperDex revolute limits are z components; MJCF hinge axes were y | Joint frames rotated so every hinge axis is +z; FK parity re-checked |
| Arm sagged 2 mrad with exact gravity feed-forward | Tracking force is 2·stiffness·error | Stiffness = kp/2; effective kp measured |
| Throughput flat beyond ~12 cores (620 steps/s at 64 envs) | Python GIL re-acquired after every Scene.step | Worker processes with shared-memory state, one message per 20 Hz tick |
| Wrist render cost 57 ms per call regardless of world count | The calibrated Warp renderer rebuilds its kernel in Python per call | CUDA-graph capture of the whole Warp sequence (bit-identical, 0.40 ms/image) |
| Bottles sank, tipped or fell through the table away from its centre | Contact sampled on a 12-triangle tabletop | Tabletop tessellated to ≤3 cm triangles; checked at 12 locations |
| Bottles tipped at reset under combined layout + physics randomization | Changing the bottle's local COM after posing moves its shape | Mass properties set before the pose |
| Randomized starts inside the table or bottle | Unfiltered joint offsets (also in mjlab_gs) | Reset guard halves offsets until the TCP clears table and bottle |
Physics validation
- Kinematics: SuperDex link poses match MuJoCo within 3.4e-07 m and 5.9e-07 rotation error over 20 random configurations.
- Drives: SuperDex tracking force is 2·stiffness·error, so stiffness = kp/2; measured effective kp 2499.9 for kp 2500.
- Gravity hold: with gravity feed-forward, maximum TCP drift 8.9e-05 mm after 2 s at 8 randomized poses in free space.
- RG2 linkage: moment/truss/tip angles agree within 0.43 mrad; pad separation matches MuJoCo's equality-coupled model within 0.021 mm from open to closed.
- Contact at rest: at 12 tabletop locations the bottle rests with at most 0.268 mm penetration and 0.00° tilt on the tessellated 4 cm slab (4992 faces). SuperDex samples contact on the colliding surface, so the plain 12-triangle slab let 1 of 12 bottles sink, tip or fall through away from its vertices; the full-height 12-face box: 4 of 12. This was found by the DR gallery and fixed before the final measurements.
- Friction mixing: SuperDex uses the geometric mean of coefficients; per-body values reproduce MuJoCo's pad–bottle 1.0 and bottle–table 0.65.
Grasp-and-lift through the action interface
A privileged scripted expert issues the same 7-D actions a policy would (approach, descend, close, lift). Each environment's first episode counts; strict success as above.
| DR preset | Start | Scale | Successes | Rate | Failure outcomes |
|---|---|---|---|---|---|
| nominal | joint | 0.0 | 16 / 16 | 100% | – |
| teacher | cartesian (49 Cartesian) | 0.3 | 56 / 56 | 100% | – |
| teacher | cartesian (21 Cartesian) | 1.0 | 51 / 56 | 91% | lifted, hold < 2 s 3, never bilaterally grasped 2 |
| teacher | joint | 0.3 | 56 / 56 | 100% | – |
| teacher | joint | 0.6 | 55 / 56 | 98% | lifted, hold < 2 s 1 |
| teacher | joint | 1.0 | 51 / 56 | 91% | lifted, hold < 2 s 3, never bilaterally grasped 2 |
| visual | joint | 0.3 | 56 / 56 | 100% | – |
| visual | joint | 0.6 | 53 / 56 | 95% | lifted, hold < 2 s 3 |
| visual | joint | 1.0 | 33 / 56 | 59% | grasped, not lifted 10 cm 3, lifted, hold < 2 s 7, never bilaterally grasped 13 |
Reachability of the randomized layouts
top-down TCP orientation (nominal, ±0.12 rad yaw), 5 mm tolerance; homotopy damped-least-squares IK from the nominal arm pose. Unreachable Cartesian starts fall back to the joint-offset start.
| Preset | Scale | Top-down grasp reachable | Cartesian start reachable |
|---|---|---|---|
| teacher | 0.3 | 120 / 120 | 107 / 120 |
| teacher | 0.6 | 92 / 120 | 58 / 120 |
| teacher | 1.0 | 58 / 120 | 37 / 120 |
| visual | 0.3 | 113 / 120 | 89 / 120 |
| visual | 0.6 | 80 / 120 | 51 / 120 |
| visual | 1.0 | 54 / 120 | 40 / 120 |
The expert never re-plans: it has no regrasp, no reorientation and no recovery after a bottle is knocked over. At full layout randomization many bottles sit outside the arm's top-down workspace (table ±30 cm, base ±20 cm), so failures there mostly reflect the distribution and the expert rather than simulator errors. Raw results are linked below.
Wrist camera and domain randomization
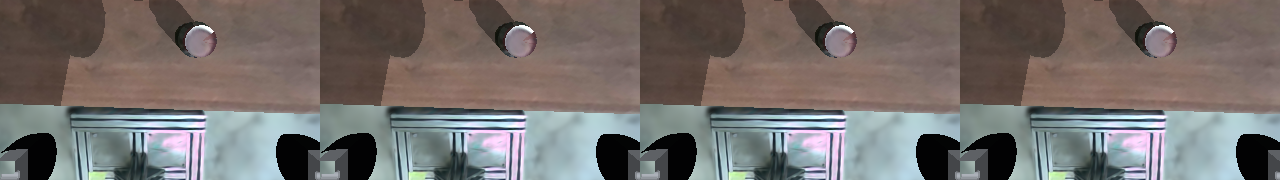
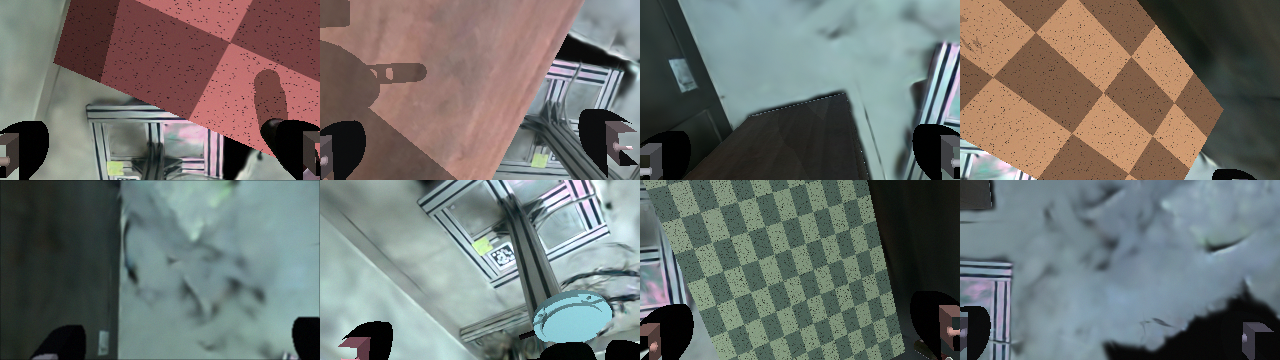
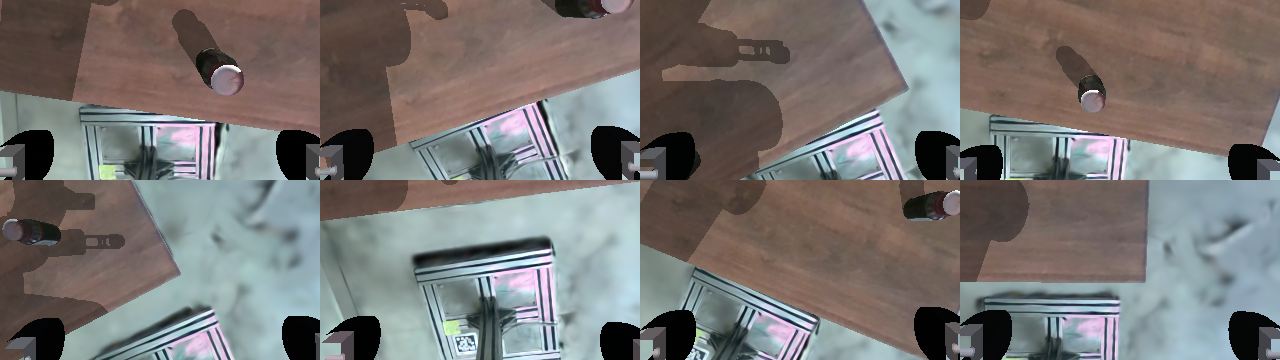
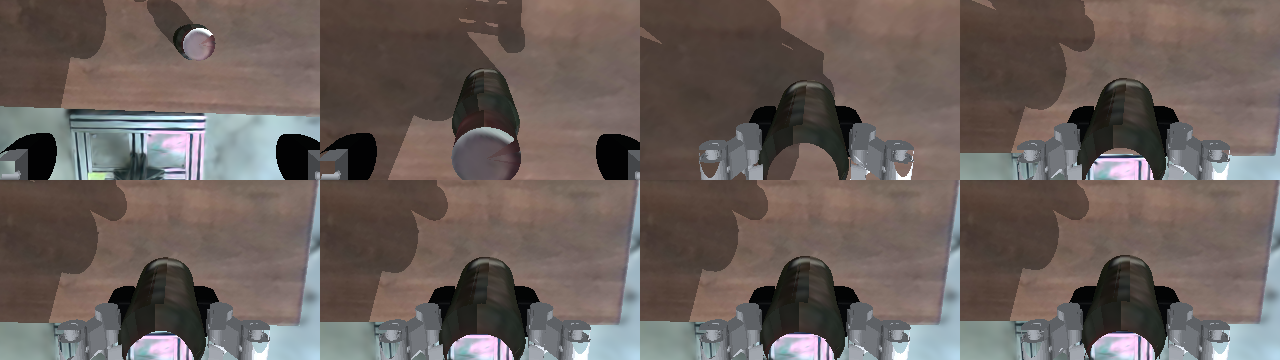
All randomized quantities (RANDOMIZATION.md)
| Family | Quantity | Range at scale 1 | Source |
|---|---|---|---|
| layout | table XY / yaw | ±0.30 m / ±30° (teacher ±0.15 m / ±15°) | MG (PT ±1.5 cm / ±1.4°) |
| layout | bottle position | interpolates nominal → uniform over tabletop minus 5 cm margin (±0.340, ±0.182 m) | MG |
| layout | bottle yaw | ±180° relative to table | MG, PT |
| layout | robot base + pedestal XY / yaw (Gaussian pedestal moves with it) | ±0.20 m / ±30° about the pedestal origin (teacher ±0.10 / ±15°) | MG (PT ±5 mm / ±1°) |
| robot_init | arm joint offsets | ±[45, 20, 30, 45, 30, 90]° (teacher ±[15, 10, 10, 15, 15, 30]°); guard halves offsets until the TCP is ≥ 4 cm above the table and clear of the bottle | MG; guard new |
| robot_init | Cartesian start (`start_mode="cartesian"`) | TCP = grasp + 17 cm stratum {11, 14.5, 18} cm, XY ±7 / ±4.5 cm, grasp yaw ±0.12 rad; IK from nominal | PT |
| robot_init | initial gripper openness | U(0.85, 1) | MG |
| physics | friction (bottle, pads, fingertips, table, floor) | ×0.7–1.3 | MG |
| physics | bottle mass + inertia | ×0.8–1.2 | MG |
| physics | bottle COM offset | ±3 mm per axis | new |
| physics | drive damping (arm kd, RG2 joint viscous) | ×0.8–1.2 | MG |
| physics | arm position gains | ×0.9–1.1 (gravity feed-forward uses the randomized gain) | new |
| physics | gripper force limit | ×0.8–1.2 | new |
| camera | mount position / rotation | ±1 cm / ±5° | MG (PT ±2 mm / ±1°) |
| camera | focal lengths fx, fy | ×(1 ± 0.02) | MG, PT |
| camera | principal point | ±6.4 / ±3.6 px of the 1280×720 sensor (0.5%) | MG, PT (rescaled to D415) |
| lighting | key light position / direction | ±0.3 m / ±0.15 per component | PT |
| lighting | key light intensity and tint | ×0.7–1.3, per-channel ×0.9–1.1 | MG, PT |
| lighting | two fill lights | each on with p = 0.5, intensity U(0, 0.3), random position above the table | PT (multi-light) |
| materials | per-material RGB gain | ×0.8–1.2 per channel, independent per material | PT (MG shared one gain) |
| materials | per-material specular | ×0.5–1.5 | PT |
| materials | table texture | p = 0.5: calibrated scan, else 2 stripe patterns (PT formula) or 3 builtin patterns | PT |
| background | Gaussian room brightness and tint | ×0.85–1.15 and ×0.95–1.05 per channel | new |
| image | exposure / white balance | ×0.85–1.15 / ×0.95–1.05 per channel | MG, PT |
| image | sensor noise | σ ~ U(0.3, 2)/255 per episode, per pixel per frame | PT (MG fixed σ) |
| image | contrast / gamma | ×0.9–1.1 each | PT augmentation |
| image | 3×3 blur | p = 0.1 per episode | PT augmentation |
| timing | action latency | one-tick delay for the episode with p = 0.2 | new |
| timing | stale camera frame | p = 0.05 per tick | new |
| timing | AR(1) correlated translation noise | σ mm (default 0), ρ 0.9 | PT (evaluation option) |
| observation_noise | teacher joints / velocities / relative positions | ±0.01 rad / ±0.05 rad/s / ±2 mm | MG/RL teacher |
| disturbance | bottle push | p = 0.2 per episode, 0.05–0.2 N horizontal, random time 4–10 s, 0.1 s | MG/RL (evaluation push schedules) as a training DR |
| goal | commanded position | nominal TCP ± 5/5/3 cm | MG |
Throughput, GPU and CPU
State task, process backend (idle hold)
| Configuration | Envs | Workers | Env steps/s | Sim s / wall s | Simulate | Observe | Render | Reset | GPU GiB | CPU cores |
|---|---|---|---|---|---|---|---|---|---|---|
| state, hold, process backend | 1 | 1 | 53 | 2.6 | 15.6 | 3.3 | 0.0 | 0.0 | 0.00 | 1.4 |
| state, hold, process backend | 8 | 8 | 334 | 16.7 | 19.4 | 4.5 | 0.0 | 0.0 | 0.00 | 5.8 |
| state, hold, process backend | 16 | 16 | 668 | 33.4 | 21.1 | 2.8 | 0.0 | 0.0 | 0.00 | 11.0 |
| state, hold, process backend | 32 | 32 | 921 | 46.1 | 30.6 | 4.1 | 0.0 | 0.0 | 0.00 | 22.8 |
| state, hold, process backend | 64 | 56 | 1,050 | 52.5 | 54.0 | 6.9 | 0.0 | 0.0 | 0.00 | 28.4 |
| state, hold, process backend | 128 | 56 | 1,282 | 64.1 | 86.5 | 13.3 | 0.0 | 0.0 | 0.00 | 29.5 |
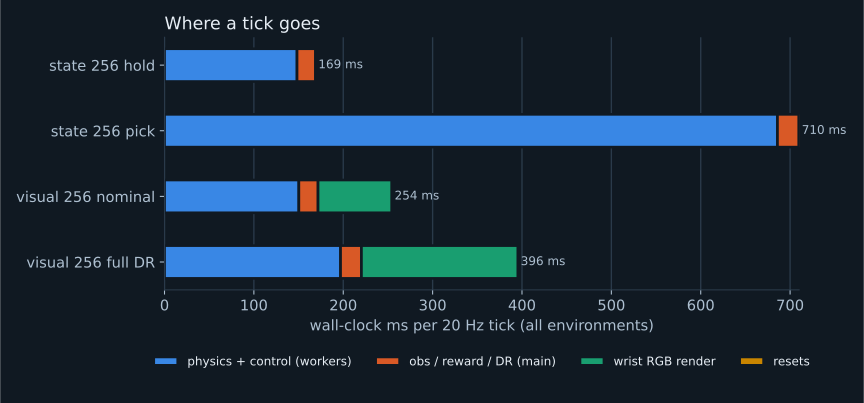
| state, hold, process backend | 256 | 56 | 1,513 | 75.7 | 148.3 | 20.8 | 0.0 | 0.0 | 0.00 | 31.2 |
| state, hold, process backend | 512 | 56 | 1,659 | 83.0 | 271.1 | 37.5 | 0.0 | 0.0 | 0.00 | 27.6 |
Times are wall-clock ms per 20 Hz tick for all environments together.
State task, thread backend (idle hold)
| Configuration | Envs | Workers | Env steps/s | Sim s / wall s | Simulate | Observe | Render | Reset | GPU GiB | CPU cores |
|---|---|---|---|---|---|---|---|---|---|---|
| state, hold, thread backend (8 threads) | 8 | 8 | 77 | 3.8 | 100.2 | 3.9 | 0.0 | 0.0 | 0.00 | 2.4 |
| state, hold, thread backend (8 threads) | 64 | 8 | 311 | 15.5 | 195.1 | 10.9 | 0.0 | 0.0 | 0.00 | 4.5 |
| state, hold, thread backend (8 threads) | 256 | 8 | 435 | 21.7 | 564.0 | 24.8 | 0.0 | 0.0 | 0.00 | 5.7 |
Times are wall-clock ms per 20 Hz tick for all environments together.
State task, scripted grasping (contact-rich)
| Configuration | Envs | Workers | Env steps/s | Sim s / wall s | Simulate | Observe | Render | Reset | GPU GiB | CPU cores |
|---|---|---|---|---|---|---|---|---|---|---|
| state, scripted pick (contact) | 16 | 16 | 188 | 9.4 | 80.8 | 3.6 | 0.0 | 0.0 | 0.00 | 12.9 |
| state, scripted pick (contact) | 64 | 56 | 269 | 13.5 | 225.3 | 10.8 | 0.0 | 0.0 | 0.00 | 27.3 |
| state, scripted pick (contact) | 256 | 56 | 359 | 17.9 | 685.9 | 24.2 | 0.0 | 0.0 | 0.00 | 31.3 |
Times are wall-clock ms per 20 Hz tick for all environments together.
Visual task 320×180, nominal
| Configuration | Envs | Workers | Env steps/s | Sim s / wall s | Simulate | Observe | Render | Reset | GPU GiB | CPU cores |
|---|---|---|---|---|---|---|---|---|---|---|
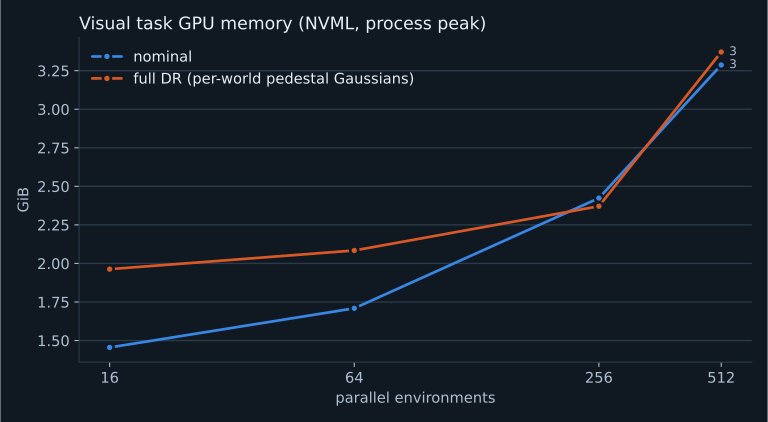
| visual 320x180, nominal | 16 | 16 | 477 | 23.8 | 23.5 | 2.4 | 7.6 | 0.0 | 1.46 | 9.3 |
| visual 320x180, nominal | 64 | 56 | 727 | 36.4 | 59.5 | 7.4 | 21.2 | 0.0 | 1.71 | 20.9 |
| visual 320x180, nominal | 256 | 56 | 1,006 | 50.3 | 150.3 | 21.5 | 82.6 | 0.0 | 2.42 | 20.6 |
| visual 320x180, nominal | 512 | 56 | 1,055 | 52.7 | 273.4 | 40.4 | 171.6 | 0.0 | 3.29 | 18.2 |
Times are wall-clock ms per 20 Hz tick for all environments together.
Visual task 320×180, full domain randomization
| Configuration | Envs | Workers | Env steps/s | Sim s / wall s | Simulate | Observe | Render | Reset | GPU GiB | CPU cores |
|---|---|---|---|---|---|---|---|---|---|---|
| visual 320x180, full DR 1.0 | 16 | 16 | 338 | 16.9 | 31.5 | 2.5 | 13.4 | 0.0 | 1.96 | 8.8 |
| visual 320x180, full DR 1.0 | 64 | 56 | 499 | 25.0 | 75.5 | 8.8 | 43.9 | 0.0 | 2.08 | 18.5 |
| visual 320x180, full DR 1.0 | 256 | 56 | 647 | 32.4 | 197.0 | 23.4 | 175.2 | 0.0 | 2.37 | 17.1 |
| visual 320x180, full DR 1.0 | 512 | 56 | 688 | 34.4 | 351.6 | 38.5 | 353.6 | 0.0 | 3.37 | 15.4 |
Times are wall-clock ms per 20 Hz tick for all environments together.
Visual scripted grasping (DR 0.3) and state hold with teacher DR 1.0
| Configuration | Envs | Workers | Env steps/s | Sim s / wall s | Simulate | Observe | Render | Reset | GPU GiB | CPU cores |
|---|---|---|---|---|---|---|---|---|---|---|
| visual 320x180, scripted pick, DR 0.3 | 64 | 56 | 227 | 11.4 | 216.5 | 11.9 | 51.9 | 0.0 | 2.09 | 20.0 |
| visual 320x180, scripted pick, DR 0.3 | 256 | 56 | 301 | 15.0 | 623.3 | 24.2 | 199.6 | 0.0 | 2.38 | 22.0 |
| state, hold, teacher DR 1.0 | 256 | 56 | 1,208 | 60.4 | 188.5 | 23.4 | 0.0 | 0.0 | 0.00 | 30.6 |
Times are wall-clock ms per 20 Hz tick for all environments together.
Worker process sweep
| Configuration | Envs | Workers | Env steps/s | Sim s / wall s | Simulate | Observe | Render | Reset | GPU GiB | CPU cores |
|---|---|---|---|---|---|---|---|---|---|---|
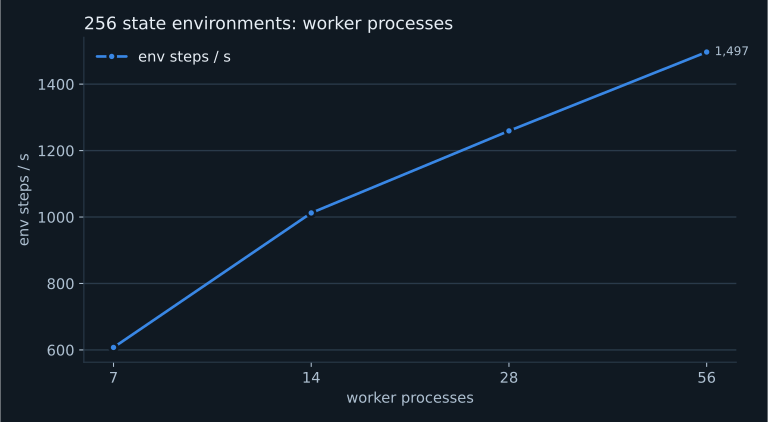
| state 256 envs, 7 workers | 256 | 7 | 607 | 30.4 | 398.4 | 23.0 | 0.0 | 0.0 | 0.00 | 6.8 |
| state 256 envs, 14 workers | 256 | 14 | 1,012 | 50.6 | 229.4 | 23.4 | 0.0 | 0.0 | 0.00 | 11.6 |
| state 256 envs, 28 workers | 256 | 28 | 1,259 | 63.0 | 180.5 | 22.8 | 0.0 | 0.0 | 0.00 | 19.7 |
| state 256 envs, 56 workers | 256 | 56 | 1,497 | 74.8 | 149.1 | 21.9 | 0.0 | 0.0 | 0.00 | 31.2 |
Times are wall-clock ms per 20 Hz tick for all environments together.
IK update rate and physics timestep
| Configuration | Envs | Workers | Env steps/s | Sim s / wall s | Simulate | Observe | Render | Reset | GPU GiB | CPU cores |
|---|---|---|---|---|---|---|---|---|---|---|
| state 128 envs, IK every 1 substeps | 128 | 56 | 841 | 42.1 | 139.3 | 12.8 | 0.0 | 0.0 | 0.00 | 31.9 |
| state 128 envs, IK every 2 substeps | 128 | 56 | 1,097 | 54.8 | 103.9 | 12.8 | 0.0 | 0.0 | 0.00 | 31.3 |
| state 128 envs, IK every 4 substeps | 128 | 56 | 1,279 | 64.0 | 87.0 | 13.1 | 0.0 | 0.0 | 0.00 | 29.5 |
| state 128 envs, IK every 8 substeps | 128 | 56 | 1,402 | 70.1 | 78.8 | 12.5 | 0.0 | 0.0 | 0.00 | 28.3 |
| state 128 envs, 1 ms physics | 128 | 56 | 748 | 37.4 | 156.8 | 14.4 | 0.0 | 0.0 | 0.00 | 31.1 |
Times are wall-clock ms per 20 Hz tick for all environments together.
Image resolution and shadows
| Configuration | Envs | Workers | Env steps/s | Sim s / wall s | Simulate | Observe | Render | Reset | GPU GiB | CPU cores |
|---|---|---|---|---|---|---|---|---|---|---|
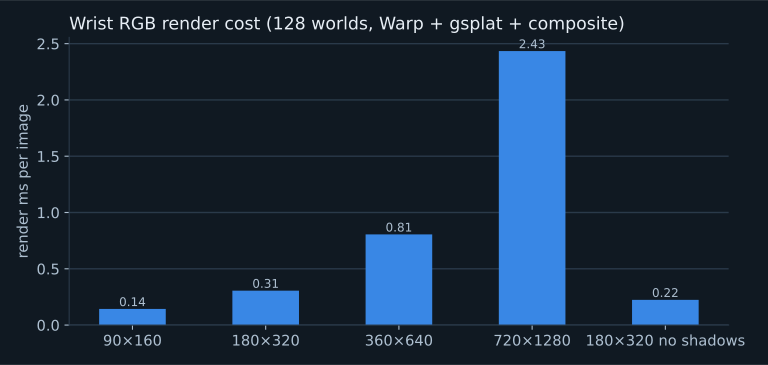
| visual 128 envs 90x160 | 128 | 56 | 1,049 | 52.4 | 90.7 | 13.0 | 18.3 | 0.0 | 1.83 | 25.6 |
| visual 128 envs 180x320 | 128 | 56 | 885 | 44.3 | 92.8 | 12.6 | 39.1 | 0.0 | 2.04 | 21.4 |
| visual 128 envs 360x640 | 128 | 56 | 608 | 30.4 | 94.2 | 13.1 | 103.1 | 0.0 | 3.20 | 14.9 |
| visual 128 envs 720x1280 | 128 | 56 | 307 | 15.4 | 93.0 | 12.0 | 311.6 | 0.0 | 9.55 | 7.3 |
| visual 128 envs 180x320 no shadows | 128 | 56 | 977 | 48.9 | 89.9 | 12.4 | 28.7 | 0.0 | 2.04 | 23.8 |
Times are wall-clock ms per 20 Hz tick for all environments together.
For reference, mjlab_gs (MuJoCo-Warp, fully on GPU) measured 10,871 state env steps/s at 1,024 worlds and 2,842 visual steps/s at 1,024 worlds with 128×128 images. superdex_gs trades that throughput for SuperDex's contact model: physics runs on CPU cores, so throughput is set by core count, and contact-rich phases cost more than idle steps.
Rendering and contact-cost studies
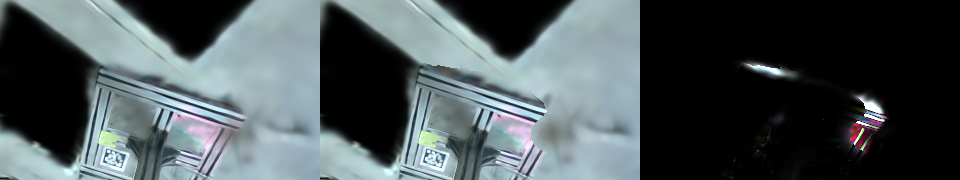
Randomized robot-base layouts. The pedestal Gaussians move with the base, so each world needs its own rasterization. The exact path (default, as mjlab_gs, chunks of 16) costs 0.59 ms per image at 256 worlds. An optional two-layer composite (room batched once, 19k pedestal Gaussians per world, depth-ordered alpha compositing) costs 0.43 ms, with background PSNR median 47.8 dB but 31.2 dB in the worst world (edge artifacts where the camera sees the pedestal), so it is not the default.
Collision-hull resolution. 16 envs, teacher DR 0.3, scripted pick; mean worker physics ms per 20 Hz tick (one world per worker). Default keeps MuJoCo full convex hulls.
| Max hull vertices | Physics ms/tick, approach | Physics ms/tick, grasp + hold | Scripted success |
|---|---|---|---|
| full (MuJoCo hulls, default) | 34.5 | 56.8 | 16/16 |
| 200 | 33.5 | 54.8 | 16/16 |
| 64 | 32.6 | 40.1 | 15/16 |
RL integration. An rsl_rl 5.5 PPO runner consumed the environment through superdex_gs.rl.RslRlEnv for 5 iterations (15,360 steps, 128 envs, 653 steps/s including updates). This checks the interface only; no teacher has been trained yet.
Unit tests: 7 passed in 2.41s
Videos
Left: third-person MuJoCo view of the same state. Right: the policy's wrist RGB (D415, Warp mesh + Gaussian room), with clearance, contact and hold overlays.
Limitations
- SuperDex physics runs on CPU: 1,659 state env steps/s at best on this machine, far below mjlab_gs's GPU physics. Rendering is not the bottleneck.
- The success monitor runs at 20 Hz (mjlab_gs checks every 1 ms substep). Robot–environment collision validity and penetration gates of mjlab_gs are not yet enforced.
- Two symmetric RG2 drives approximate the single geared actuator; left/right fingers are not kinematically coupled.
- Gaussian regions cannot be relit; lighting DR affects mesh foreground only, and a separate background gain/tint approximates appearance changes. No distractors, lens distortion, rolling shutter or depth noise.
- D415 mount hand-eye calibration is the CAD pose (unmeasured). No teacher or student has been trained in superdex_gs yet; the rsl_rl adapter is an integration check only.
Raw artifacts
benchmark/ik_period_1.json · benchmark/ik_period_2.json · benchmark/ik_period_4.json · benchmark/ik_period_8.json · benchmark/image_180x320.json · benchmark/image_180x320_noshadow.json · benchmark/image_360x640.json · benchmark/image_720x1280.json · benchmark/image_90x160.json · benchmark/physics_dt_1ms.json · benchmark/state_hold_sweep.json · benchmark/state_hold_sweep_threads.json · benchmark/state_hold_teacher_dr.json · benchmark/state_pick_sweep.json · benchmark/visual_hold_fulldr.json · benchmark/visual_hold_nominal.json · benchmark/visual_pick_dr03.json · benchmark/workers_14.json · benchmark/workers_28.json · benchmark/workers_56.json · benchmark/workers_7.json · reports/physics_checks.json · reports/fk_parity.json · reports/scene_build.json · reports/contract_visual.json · pick/nominal.json · pick/teacher_cartesian_0.3.json · pick/teacher_cartesian_1.0.json · pick/teacher_joint_0.3.json · pick/teacher_joint_0.6.json · pick/teacher_joint_1.0.json · pick/visual_joint_0.3.json · pick/visual_joint_0.6.json · pick/visual_joint_1.0.json
Built 2026-09-14T23:03:20+00:00 · Physics-only simulator experiments · RL training · mjlab_gs